Abstract
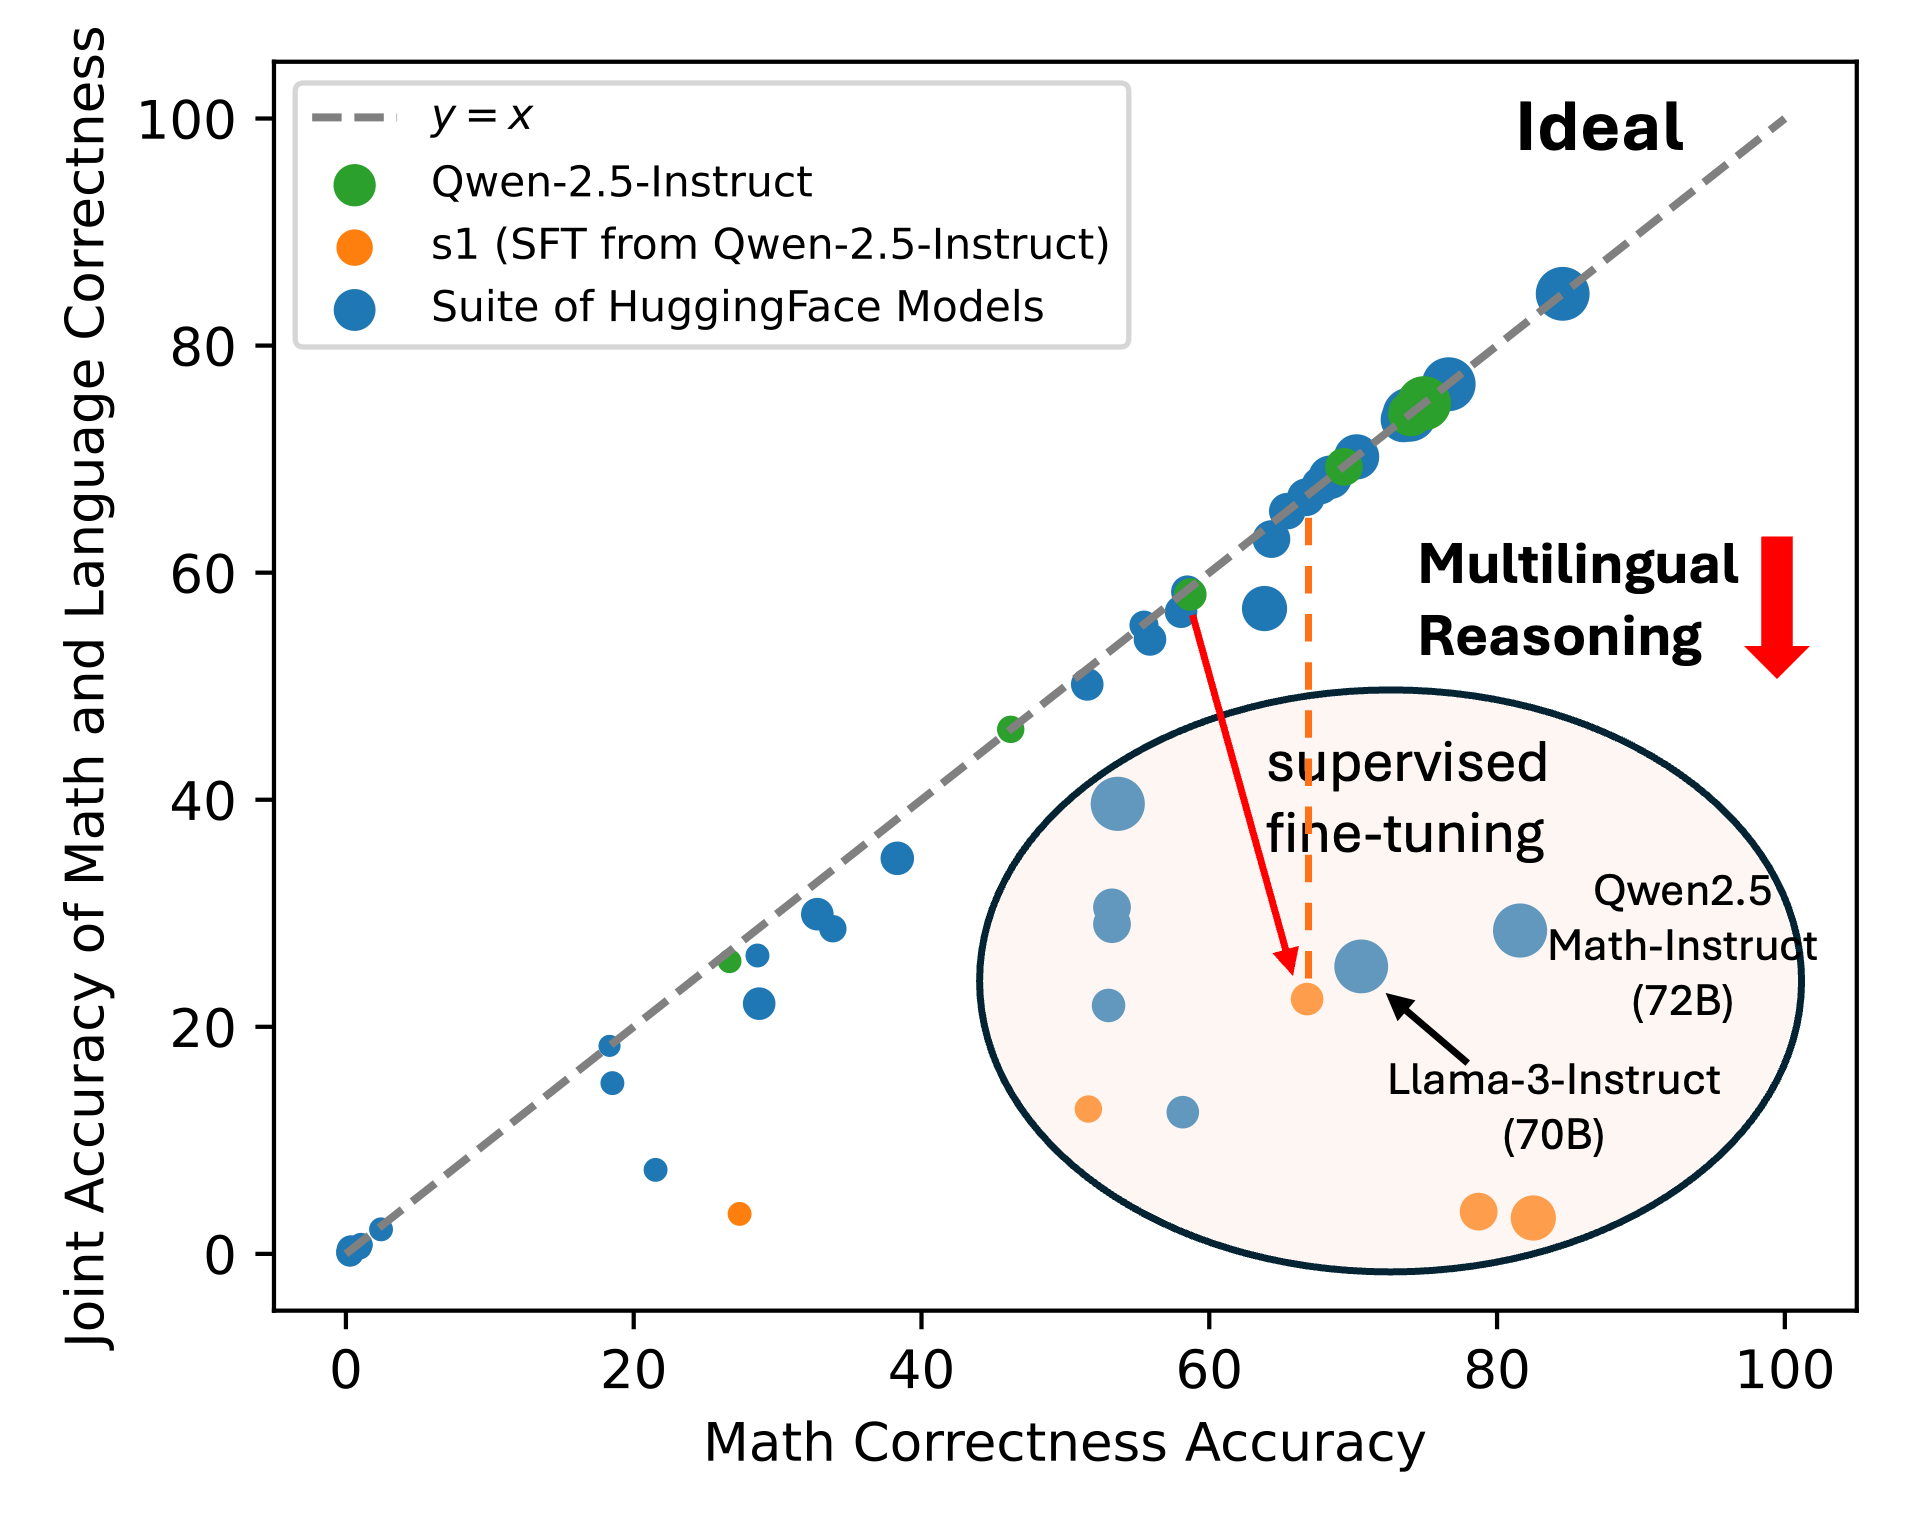
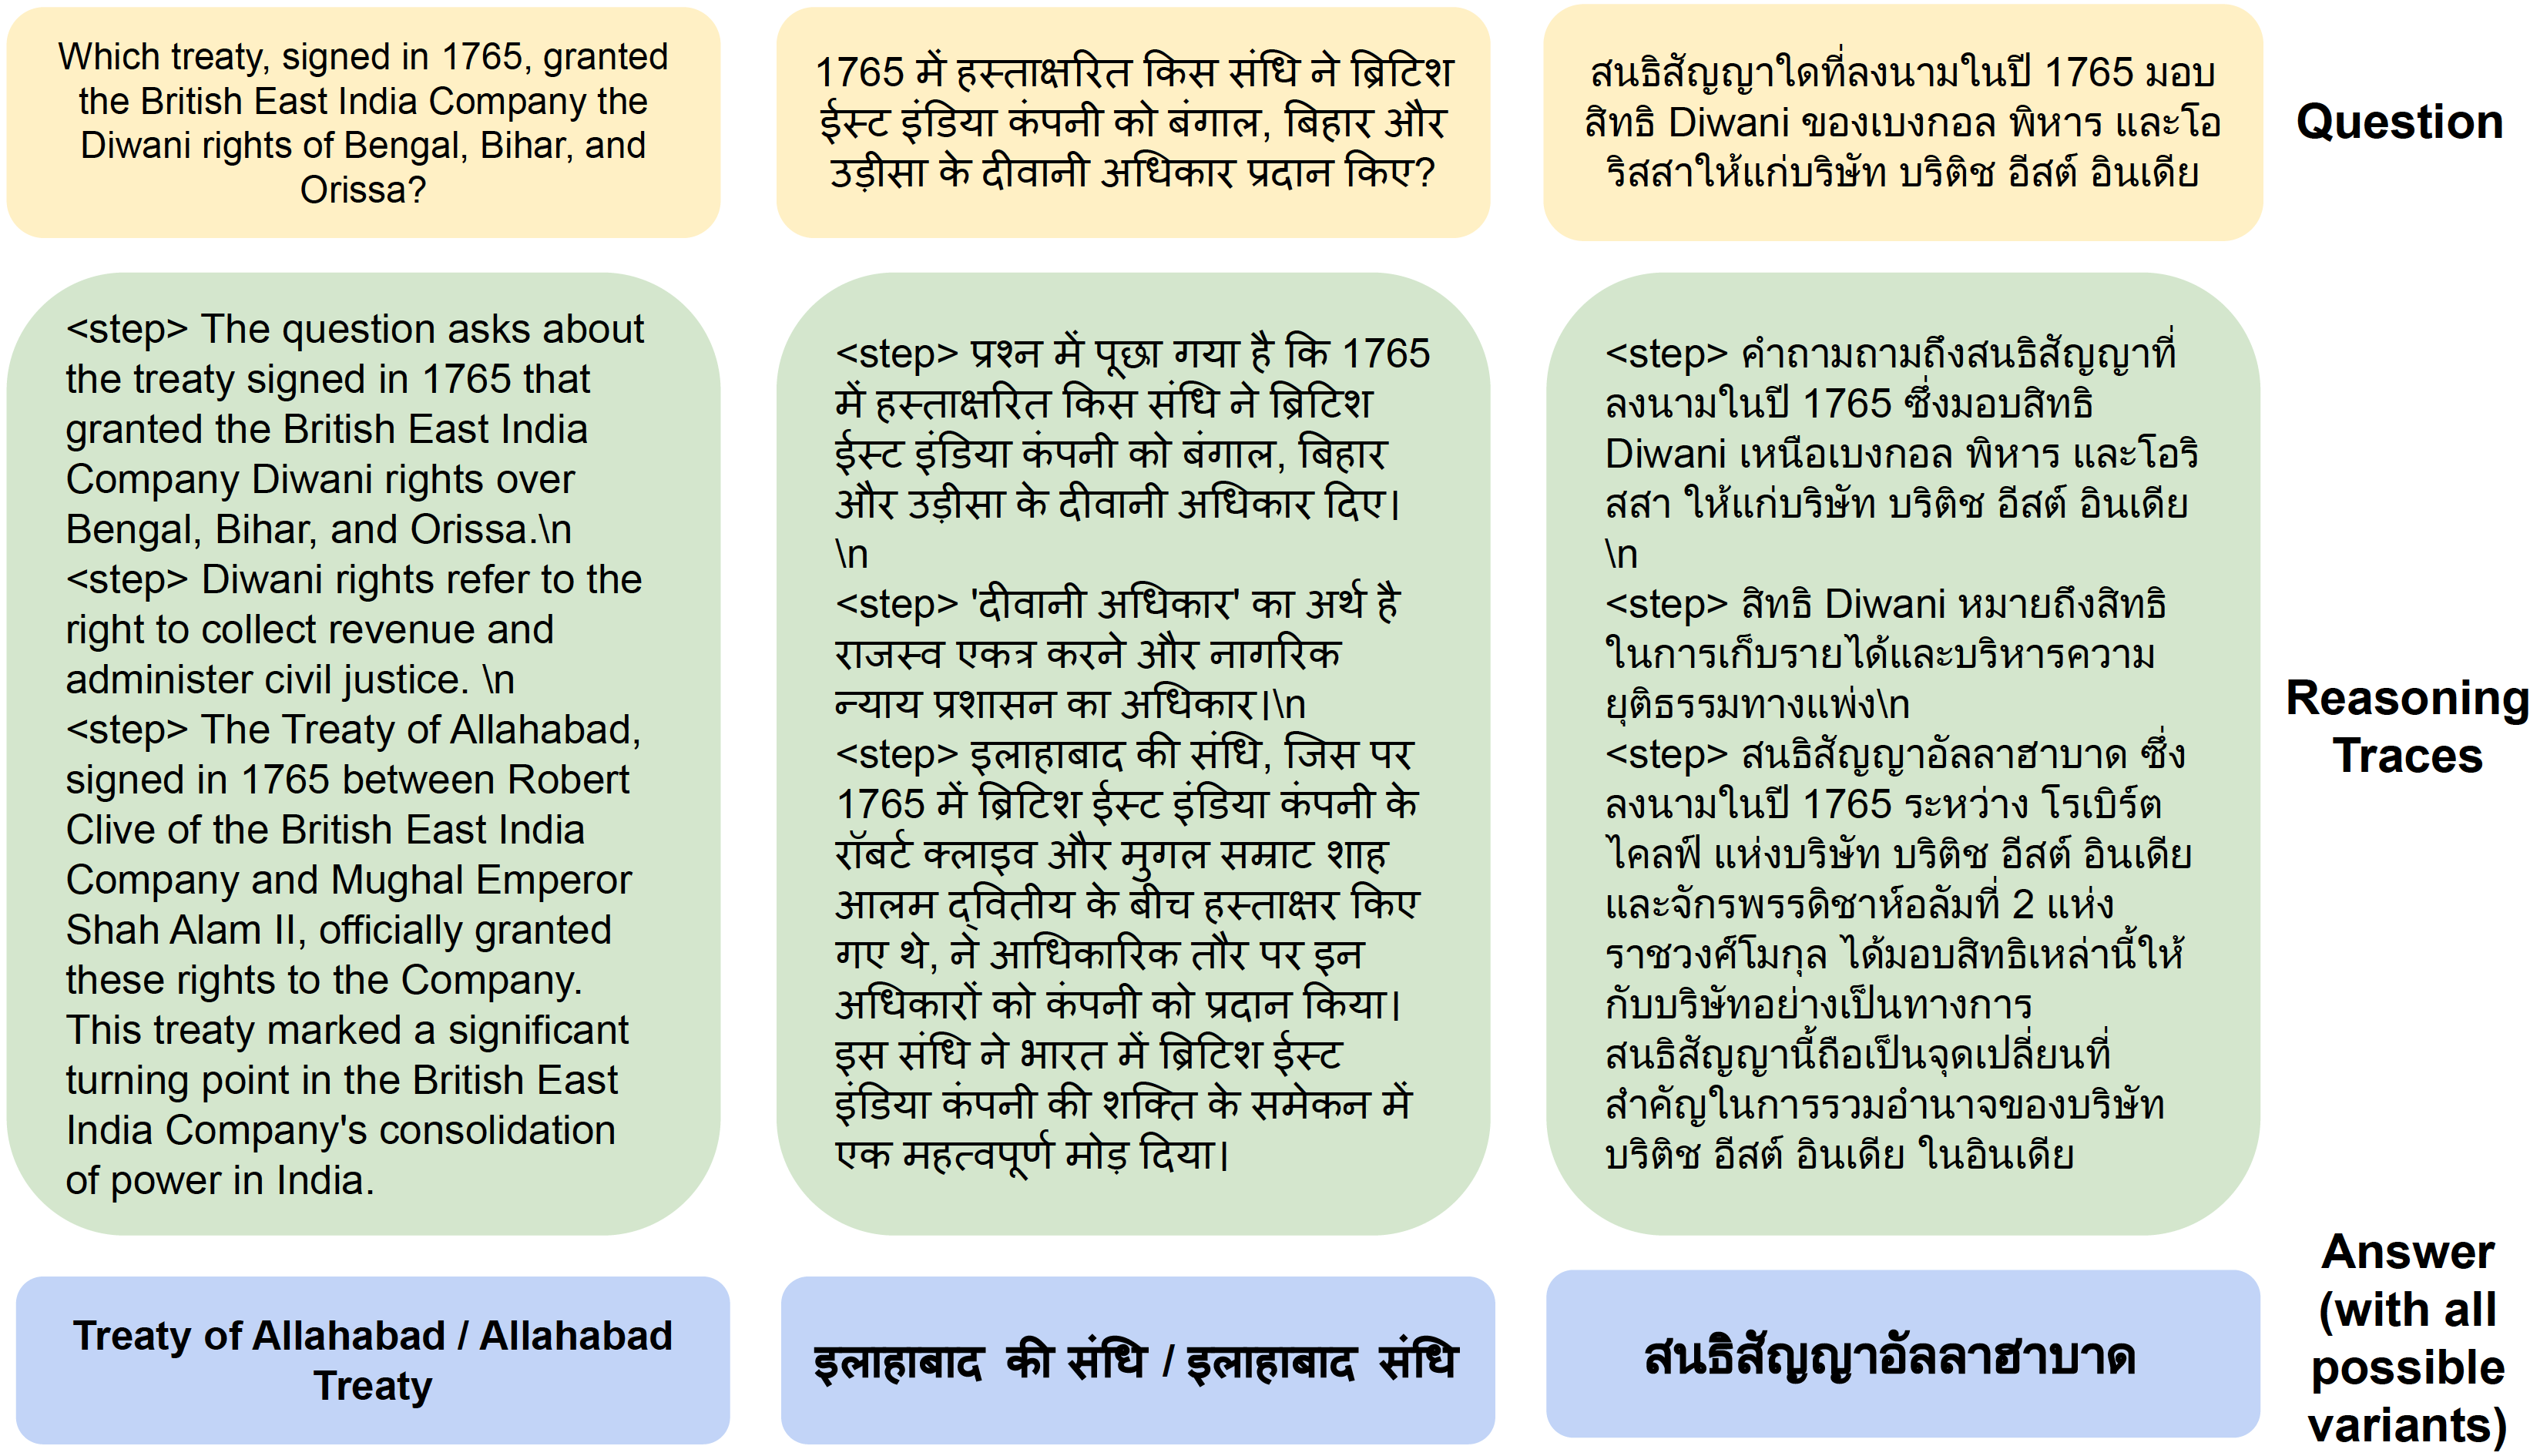
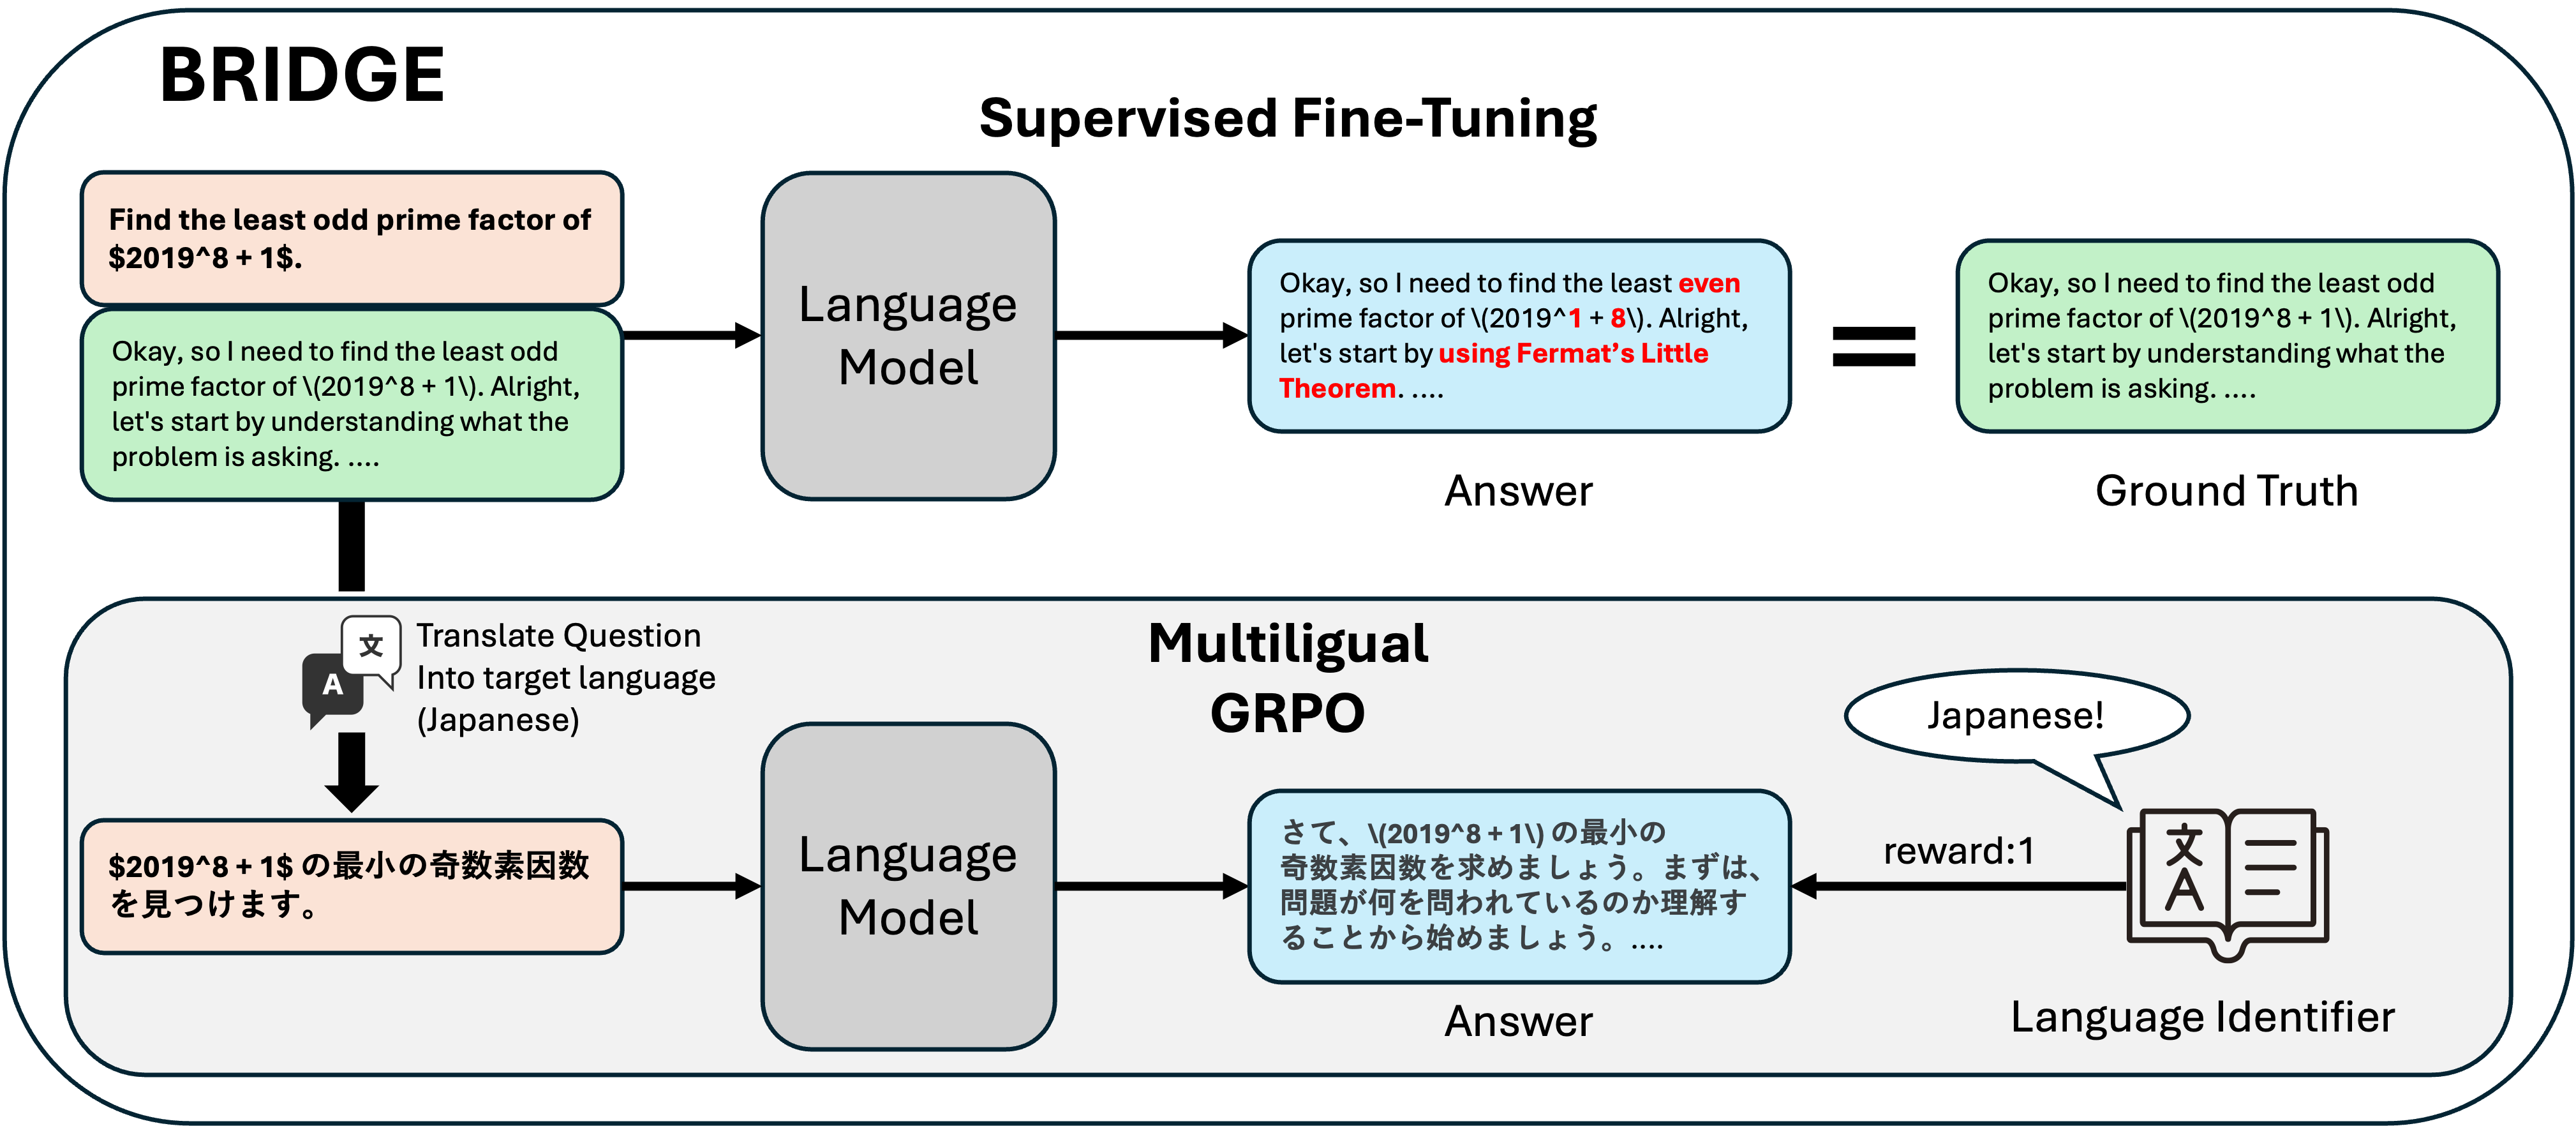
Large Language Models (LLMs) have achieved strong performance in domains like mathematics, factual QA, and code generation, yet their multilingual reasoning capabilities in these tasks remain underdeveloped. Especially for low-resource languages such as Swahili or Thai, LLMs can often misinterpret prompts or default to reasoning in English. This implicit bias toward high-resource languages undermines factual accuracy, interpretability, and trust. Current multilingual benchmarks focus only on final answers, overlooking whether models actually reason in the target language. To address this gap, we introduce GeoFact-X, a geography-based multilingual factual reasoning benchmark with annotated reasoning traces in five languages: English, Hindi, Japanese, Swahili, and Thai. We further propose BRIDGE, a novel training method that guides supervised fine-tuning and test-time reinforcement learning with a language-consistency reward to align reasoning with the input language. Finally, we develop an automatic evaluation protocol using LLM-as-a-judge to assess answer correctness and the quality and language consistency of reasoning traces, enabling nuanced and scalable analysis beyond surface-level metrics. Our results show that BRIDGE significantly enhances multilingual reasoning fidelity, demonstrating that reasoning-aware multilingual reinforcement learning is crucial for robust cross-lingual generalization.
GeoFact-X Dataset
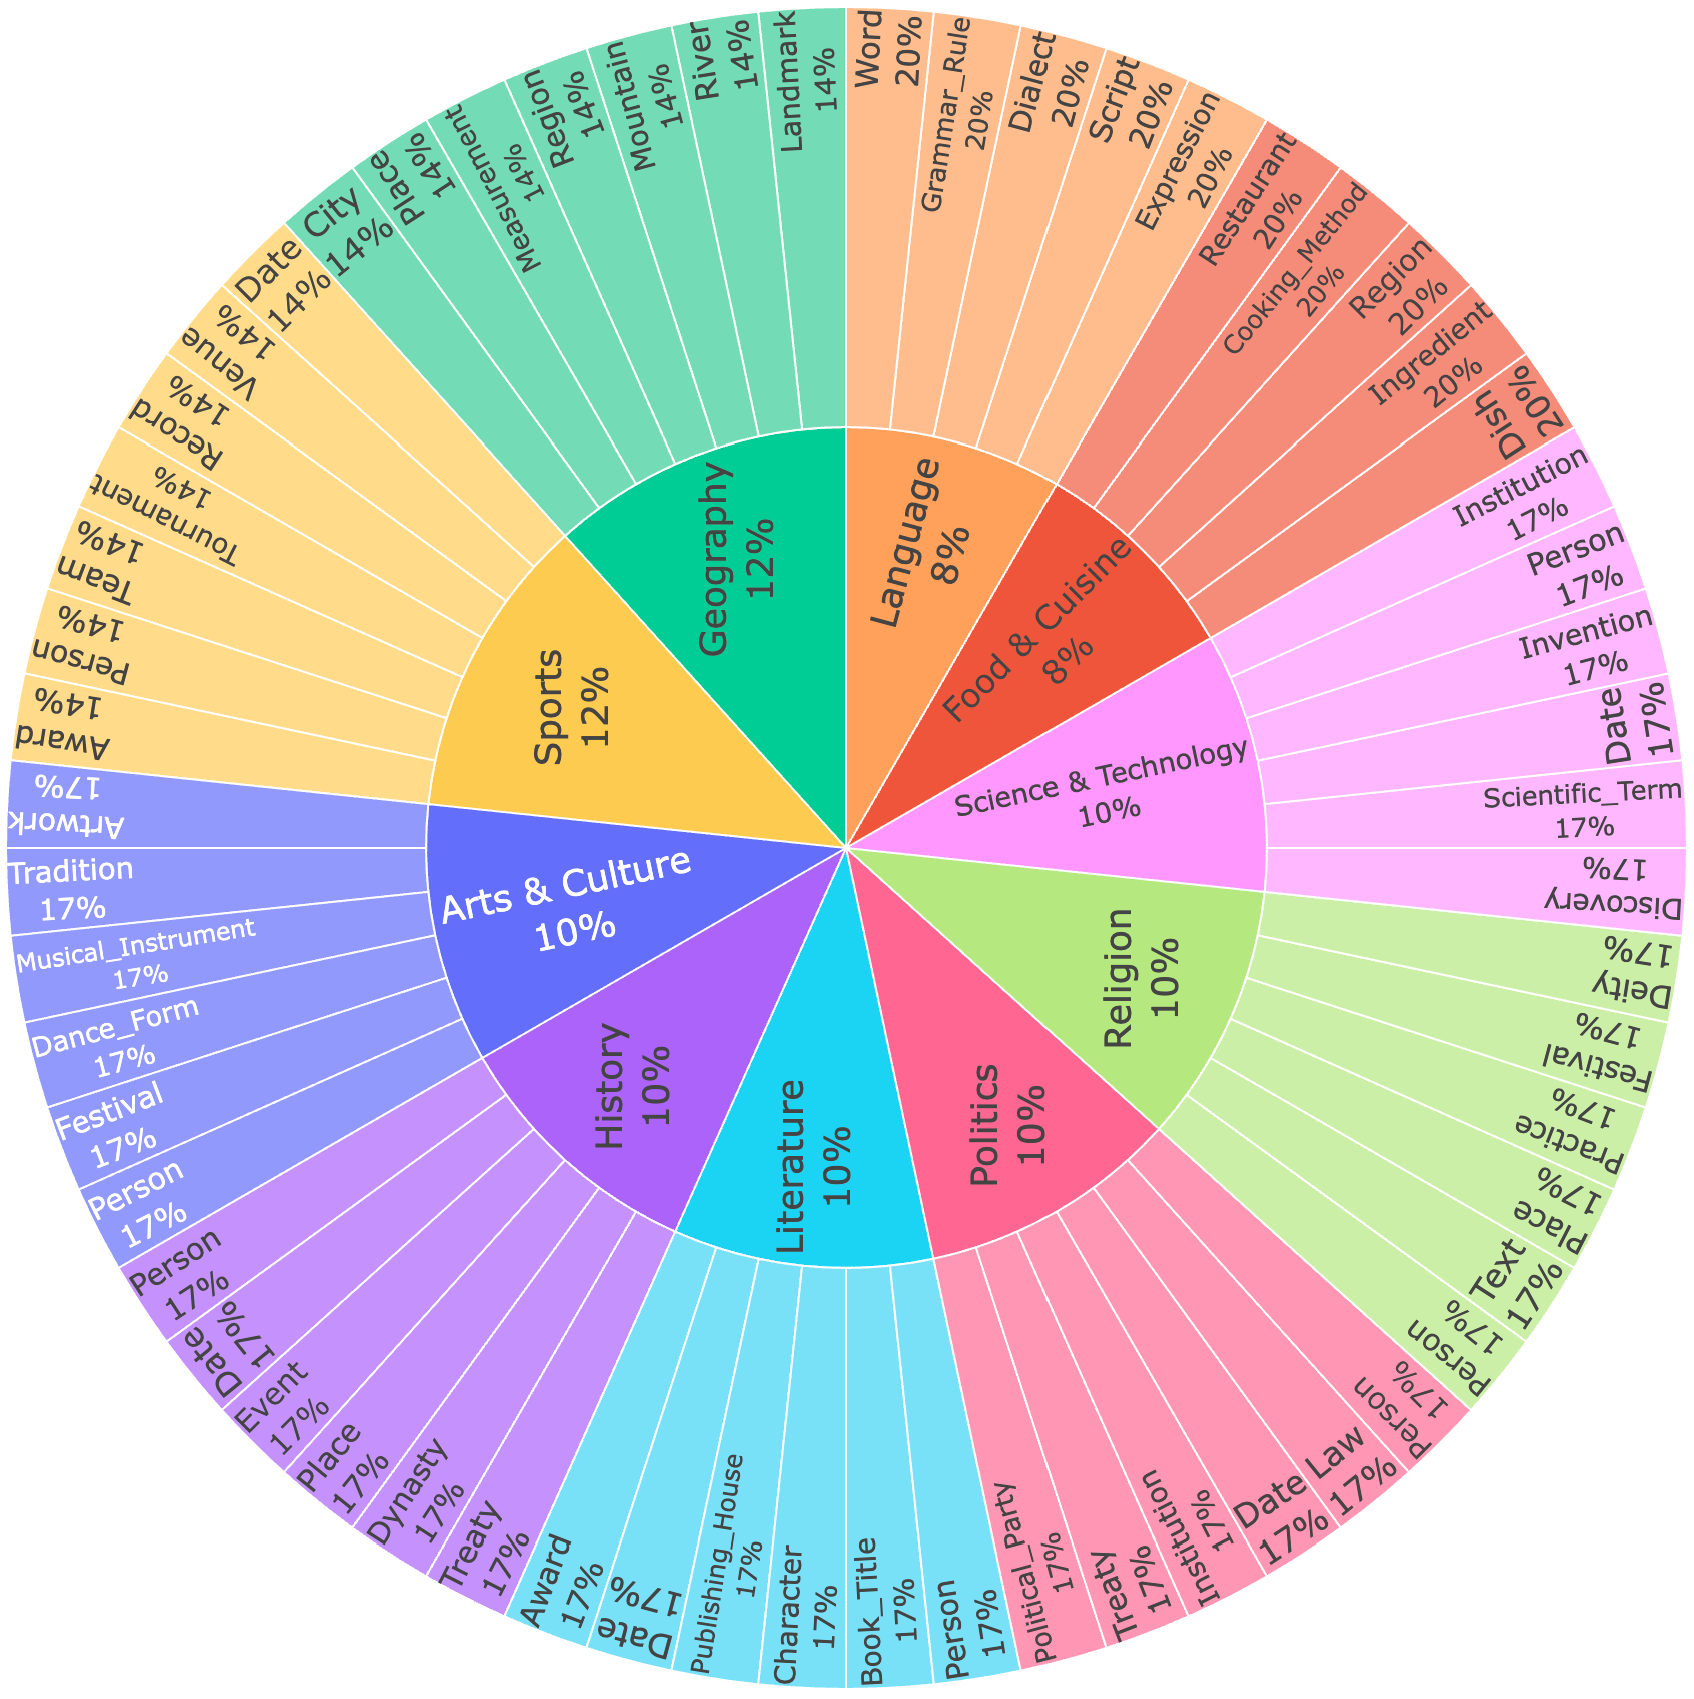
We introduce a multilingual factual reasoning dataset specifically designed to evaluate factual accuracy and reasoning capabilities across diverse linguistic and cultural contexts. Leveraging Gemini 2.0 Flash, we generate 3,000 unique factual questions (approximately 600 per country) covering locally grounded topics such as history, politics, geography, art, and culture, localized to five geographically distinct countries: the USA, India, Japan, Kenya, and Thailand. The dataset is available in the predominant local languages: English, Hindi, Japanese, Swahili, and Thai. Our goal is to capture country-specific factual knowledge, encouraging language models to reason effectively within culturally contextualized knowledge spaces.
BRIDGE
Experiments
Factual Reasoning
| Model | Average Reasoning Score (%) ↑ | Average Language Mismatch (%) ↓ | Average Answer Correctness (%) ↑ | ||||||
|---|---|---|---|---|---|---|---|---|---|
| All | Assoc. | Non-Assoc. | All | Assoc. | Non-Assoc. | All | Assoc. | Non-Assoc. | |
| Qwen2.5-Instruct | 45.6 | 49.6 | 44.6 | 14.2 | 9.9 | 15.3 | 28.6 | 36.7 | 26.6 |
| GRPO | 43.9 ± 0.3 | 45.9 ± 0.3 | 43.4 ± 0.3 | 0.9 ± 0.1 | 0.2 ± 0.1 | 1.0 ± 0.1 | 28.6 ± 0.0 | 31.7 ± 0.4 | 27.8 ± 0.1 |
| SFT | 45.6 ± 0.2 | 49.1 ± 0.5 | 44.7 ± 0.2 | 1.3 ± 0.1 | 0.9 ± 0.5 | 1.3 ± 0.1 | 29.4 ± 0.1 | 35.4 ± 0.9 | 27.9 ± 0.3 |
| BRIDGE | 45.7 ± 0.1 | 49.0 ± 0.5 | 44.9 ± 0.2 | 1.1 ± 0.2 | 0.8 ± 0.2 | 1.2 ± 0.2 | 30.0 ± 0.2 | 36.1 ± 1.0 | 28.5 ± 0.4 |
All methods perform better on associated pairs than on non‑associated pairs and consistently reduce language mismatch. However, both reasoning score and answer correctness on associative pairs decrease since GeoFact-X includes more non-associative pairs. BRIDGE achieves the strongest performance across all metrics when evaluated on the full test set, followed by SFT.
Mathematical Reasoning
| Method | GSM8K ↑ | MGSM ↑ | ||||
|---|---|---|---|---|---|---|
| Math. | Lang. | Joint | Math. | Lang. | Joint | |
| Qwen-2.5-Instruct | 81.2 | 100 | 81.2 | 58.7 | 99.0 | 58.1 |
| GRPO | 80.4 ± 0.9 | 100.0 ± 0.0 | 80.4 ± 0.9 | 58.8 ± 0.4 | 95.9 ± 2.9 | 58.2 ± 0.7 |
| SFT (s1) | 87.2 ± 1.6 | 100.0 ± 0.0 | 87.2 ± 1.6 | 66.7 ± 0.1 | 31.0 ± 0.5 | 21.9 ± 0.6 |
| SFT on s1K-X | 84.3 ± 1.1 | 66.7 ± 33.3 | 56.5 ± 28.3 | 45.2 ± 4.1 | 99.7 ± 0.1 | 45.0 ± 4.3 |
| BRIDGE | 87.9 ± 0.5 | 100.0 ± 0.0 | 87.9 ± 0.5 | 59.1 ± 0.2 | 95.0 ± 3.5 | 55.5 ± 2.7 |
| BRIDGE (ja only) | 90.3 ± 0.4 | 99.9 ± 0.1 | 90.3 ± 0.4 | 64.9 ± 0.8 | 64.6 ± 9.7 | 44.9 ± 6.2 |
Table compares the base model Qwen2.5-7B-Instruct with various post-training methods, including supervised fine-tuning (SFT) and our proposed method, BRIDGE. While SFT on s1K-1.1 improves mathematical reasoning, it harms multilingual performance on MGSM; s1K-X preserves multilingual ability but at the cost of math accuracy. In contrast, BRIDGE achieves strong math performance on GSM8K, preserves multilingual reasoning better than SFT on MGSM, and yields superior joint accuracy.
Citation
@article{hwang2025learn,
    title   = {Learn Globally, Speak Locally: Bridging the Gaps in Multilingual
               Reasoning},
    author  = {Hwang, Jaedong and Tanmay, Kumar and Lee, Seok-Jin and Agrawal, Ayush
               and Palangi, Hamid and Ayush, Kumar and Fiete, Ila R and Liang, Paul Pu},
    journal = {arXiv preprint arXiv:2507.05418},
    year    = {2025},
}